Practical RAG and LLM Augmentation for Enterprises: Architecture, Data Pipelines, and Cost Optimization
In the rapidly evolving landscape of enterprise AI, leveraging Retrieval-Augmented Generation (RAG) and Large Language Models (LLMs) has become a game-changer. These technologies empower organizations to build more responsive, accurate, and scalable AI systems. However, deploying RAG and LLMs at scale involves complex architecture patterns, efficient data pipelines, and careful cost management. This comprehensive guide aims to demystify these elements, offering actionable insights for CTOs, data scientists, and enterprise architects.
—
Understanding the Power of RAG and LLMs in Enterprise Contexts
Retrieval-Augmented Generation (RAG) combines the strengths of knowledge retrieval systems with the generative capabilities of LLMs like GPT-4, enabling enterprises to create AI solutions that are both accurate and contextually grounded. Unlike standalone language models, RAG systems dynamically fetch relevant information from structured or unstructured data sources, enhancing the quality and relevance of generated outputs.
Why RAG and LLMs are Critical for Enterprises
- Enhanced accuracy: By grounding outputs in retrieved data, RAG reduces hallucinations common in LLMs.
- Scalability: Modular architecture enables handling vast data sources efficiently.
- Cost efficiency: Targeted retrieval minimizes API calls to expensive LLM endpoints.
- Regulatory compliance: Better control over data, provenance, and explainability.
Core Architecture Patterns for RAG and LLM Augmentation
Designing effective architecture is crucial for maximizing RAG and LLM capabilities while managing operational costs.
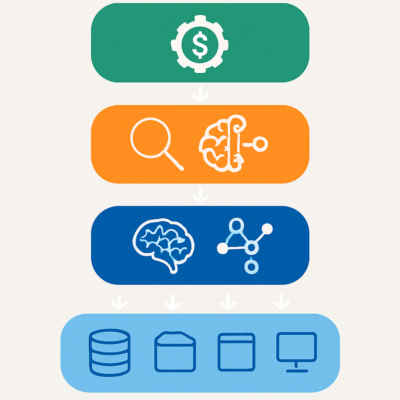
1. Modular Microservices Architecture
This pattern involves decoupling retrieval, generation, and orchestration components into independent microservices, facilitating scalability and maintainability.
- Retrieval Service: Handles indexing and querying structured/unstructured data.
- Generation Service: Hosts the LLM or prompts API.
- Orchestration Layer: Coordinates data flow between retrieval and generation.
2. Data-Driven Hybrid Pipelines
Combine batch and real-time data pipelines to keep knowledge bases current.
- Batch ETL Processes: Regularly update knowledge corpora.
- Stream Processing: Handle urgent, real-time retrieval needs.
3. Edge & Cloud Hybrid Deployment
Leverage cloud for scalable compute and storage while deploying lightweight retrieval components at the edge for latency-sensitive applications.
4. Containerized and Serverless Architectures
Utilize Docker containers and serverless functions (e.g., AWS Lambda) for flexible, cost-effective scaling.
Building Efficient Data Pipelines for RAG
A robust data pipeline ensures high-quality, timely data for retrieval components.
Data Collection & Ingestion
- Use APIs, web scraping, or data lakes to collect enterprise data.
- Prioritize structured data for accurate retrieval.
Data Processing & Indexing
- Clean and normalize data.
- Use vector databases (like Pinecone, Weaviate) for semantic search.
- Generate embeddings using models like OpenAI’s embeddings API or open-source alternatives.
Knowledge Base Maintenance
- Automate periodic updates.
- Incorporate feedback loops to improve retrieval relevance.
Retrieval Techniques
- Implement keyword-based retrieval for simple tasks.
- Use semantic search for complex, context-aware queries.
Cost Control Strategies for Enterprise RAG & LLM Projects
Balancing performance and cost is paramount.
1. Selective Retrieval
- Retrieve only the most relevant documents to reduce API calls.
- Use ranking algorithms to filter initial results.
2. On-Premises or Hybrid Models
- For sensitive data, deploy local retrieval systems.
- Combine with cloud LLM API calls for generation.
3. Optimize API Usage
- Cache frequent queries.
- Fine-tune prompts to reduce token consumption.
4. Use of Open-Source Models
- Deploy open-source LLMs (like Llama, Falcon) for in-house processing.
- Reduce dependency on costly API calls.
5. Cost Monitoring & Analytics
- Implement dedicated dashboards.
- Use anomaly detection to spot unexpected cost spikes.
Case Study: Enterprise RAG Deployment in Healthcare
An industrial healthcare provider integrated RAG to improve clinical documentation and decision support.
- Architecture: Modular microservices with an on-prem knowledge base.
- Pipeline: nightly batch updates and real-time retrieval for urgent queries.
- Cost Control: selective retrieval and caching strategies reduced API costs by 40%.
- Outcome: improved relevance and compliance, faster decision-making.
Implementation Roadmap: From Proof of Concept to Production
Step 1: Define Use Case & Success Metrics
- Clarify retrieval scope, privacy needs, and operational KPIs.
Step 2: Pilot with a Small Data Subset
- Validate retrieval accuracy and LLM responsiveness.
Step 3: Develop Scalable Data Pipelines
- Automate ingestion, processing, and indexing.
Step 4: Establish Cost Controls & Monitoring
- Implement quota management and analytics dashboards.
Step 5: Gradually Scale & Optimize
- Expand knowledge bases and refine retrieval algorithms.
Conclusion
Implementing RAG and LLM augmentation in enterprise environments opens new horizons for AI-driven innovation. By adopting scalable architecture patterns, building robust data pipelines, and strategically controlling costs, organizations can achieve measurable ROI while maintaining compliance and agility. MG Systems & Software LLC offers expert consulting to guide you through every stage—from proof of concept to full deployment—ensuring you harness the full potential of these transformative technologies.